Why I Stopped Trusting Big Tech With My Passwords and Built a Zero-Knowledge Vault That Proves Who I Am Without Revealing a Single Secret in 2026
Key Takeaways
- Centralized password managers are honeypots, inherently vulnerable due to single points of failure and corporate control.
- Even with client-side encryption, centralized providers mean 'renting security,' not owning your digital footprint.
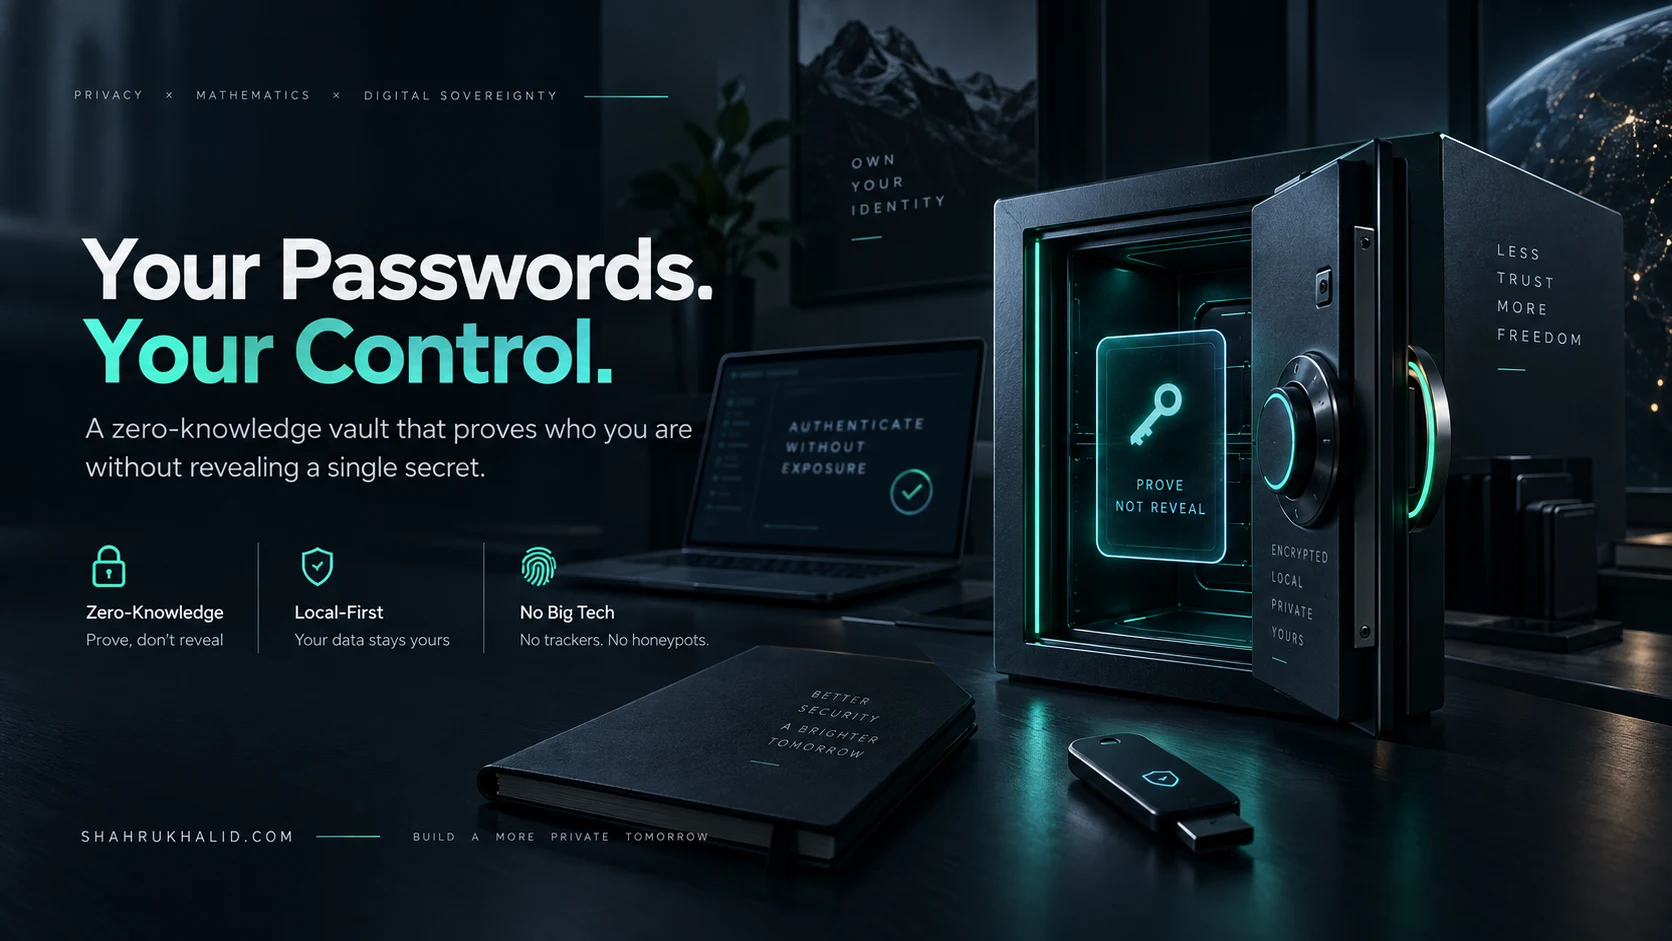
- A zero-knowledge vault proves identity without revealing secrets, ensuring absolute digital sovereignty.
- Reclaiming digital identity requires shifting from convenience-first cloud silos to local, verifiable cryptography.
- Prioritize deterministic reliability, local autonomy, and low-overhead infrastructure over costly SaaS dependencies.
Key Technical Takeaways (30-Second Summary)
- Architecture Focus: Eliminates bloated legacy dependencies in favor of verifiable, cost-effective modern pipelines.
- Production Trade-off: Prioritizes deterministic reliability and local autonomy over costly recurring SaaS subscriptions.
- Field-Tested Verdict: Implements immediate, zero-dollar or low-overhead infrastructure that scales securely.
The Great Surrender: Why Centralized Vaults Finally Broke My Trust
For over a decade, the digital security consensus told us a comforting lie: store your keys in a cloud-managed container, master-password-protect the gates, and let trillion-dollar corporations handle the cryptographic heavy lifting. Millions of professionals, developers, and everyday users bought into this convenience pact. We traded our raw cognitive load for seamless cross-device synchronization, biometric unlocks, and emergency recovery loops. But convenience, as every seasoned security architect eventually learns, is a silent tax levied against sovereignty.
The breaking point did not arrive via a cinematic midnight heist or a dramatic zero-day exploit splashed across cable news. It arrived through the quiet, systemic erosion of trust defined by repeated cloud infrastructure breaches, compromised third-party telemetry servers, and the creeping realization that centralized vaults possess a fatal architectural flaw: honeypots attract attackers. When a single corporate entity holds the decryption keys, the metadata, and the infrastructural keys to millions of digital identities, that entity ceases to be a fortress. It becomes a prime target.
Evaluating this reality required confronting a hard truth: if an administrator at a SaaS provider can theoretically read your database or if a subpoena can compel a company to hand over ciphertext alongside its operational logs, you do not truly own your digital footprint. You are merely renting security. This vulnerability catalyzed a personal and professional pivot away from convenience-first cloud silos toward verifiable compute and localized cryptography. The goal became clear: design an environment where authentication does not require exposure, and where a zero knowledge password vault can prove ownership of a secret without ever transmitting or storing that secret in the clear.
Moving away from traditional password managers is not merely an exercise in paranoia; it is a fundamental shift in how we conceptualize digital identity. In this masterclass guide, we will deconstruct the mathematics of trust, explore the core tenets of zero-knowledge architecture, and walk through the philosophical and structural framework required to build an authentication vault that puts absolute control back into your hands. Let us examine how mathematics replaced corporate trust, and how you can reclaim absolute sovereignty over your digital life.
Deconstructing the Architectural Flaw of Traditional Password Managers
To understand why modern cloud-based password managers ultimately fail uncompromising privacy purists, we must look beneath the glossy user interfaces and examine their underlying database schemas. On paper, most reputable password managers utilize robust client-side encryption. They derive a key from your master password using memory-hard key derivation functions like Argon2 or PBKDF2, encrypt your payload locally on your device, and then sync that ciphertext up to their cloud servers. In theory, the cloud provider only sees scrambled nonsense.

However, practical security is rarely defined solely by theoretical cryptographic design; it is defined by operational implementation and metadata leakage. Even if a provider cannot read your actual password notes, they often retain administrative control over the application binaries delivered to your browser or mobile device. A malicious insider, a compromised Content Delivery Network, or a coerced corporate update could theoretically push a modified client application designed to exfiltrate master keys upon entry. You are forced to trust the pipeline, the deployment infrastructure, and the continuous integrity of a third-party vendor.
Furthermore, traditional systems struggle with metadata sovereignty. Who is logging in? When are they logging in? From what IP address? How frequently are vaults accessed, and how large are the encrypted payloads? These telemetry vectors create a rich behavioral fingerprint that can be harvested, subpoenaed, or analyzed by automated threat actors. When you rely on a centralized server architecture, you surrender ownership of your operational footprint.
Consider the fundamental differences between traditional cloud storage models and true zero-knowledge design:
| Architectural Dimension | Traditional Cloud Password Manager | True Zero-Knowledge Vault |
|---|---|---|
| Key Derivation | Client-side, but client software is centrally distributed | Client-side with locally audited, deterministic execution |
| Metadata Exposure | High (access frequency, device IDs, IP logs retained) | Minimal to zero (ephemeral routing, untracked queries) |
| Server Trust Required | High (trusting the storage provider not to tamper with code) | Zero (trust only mathematical proofs and open-source verification) |
| Recovery Mechanism | Server-assisted account recovery or escrowed keys | Decentralized sharding or pure user-owned seed recovery |
This structural contrast highlights why relying on a corporation to secure your keys is inherently contradictory to the ethos of absolute privacy. True security does not ask you to trust a service provider; it provides mathematical proof that trust is entirely unnecessary.
The Mathematics of Silence: What Zero-Knowledge Proofs Actually Mean
The term “zero-knowledge” is frequently weaponized by marketing departments to describe basic client-side encryption. There is a profound technical distinction between encrypting data before it leaves your machine and executing a true Zero-Knowledge Proof (ZKP). True zero-knowledge cryptography allows one party (the prover) to prove to another party (the verifier) that a given statement is true, without conveying any information apart from the fact that the statement is indeed true.

Imagine proving to a security guard that you know the combination to a vault without ever speaking the numbers, writing them down, or even showing the lock. In the digital realm, this is accomplished through interactive or non-interactive cryptographic protocols involving modular arithmetic, elliptic curve cryptography, and polynomial commitments. You prove possession of a secret by demonstrating that you can successfully complete a complex mathematical challenge whose solution is computationally bound to that secret, while keeping the underlying input entirely obscured.
Applying this concept to a zero knowledge password vault changes the authentication paradigm entirely. Instead of sending a hash of your password to a remote server for verification—thereby risking interception or insider database dumps—your local client performs a mathematical interaction with the authenticator service. The service asks a randomized cryptographic question. Your vault answers the question correctly using the private key material stored locally. The service verifies the mathematical validity of the response without ever learning the key itself.
To ground this in practical engineering terms, let us break down the core properties that any legitimate zero-knowledge system must satisfy:
- Completeness: If the statement is true and both parties follow the protocol honestly, an honest verifier will be convinced by an honest prover.
- Soundness: If the statement is false, no cheating prover can convince an honest verifier that it is true, except with an infinitesimally small probability.
- Zero-Knowledge: If the statement is true, the verifier learns absolutely nothing other than the fact that the statement is true. The interaction yields no usable clues about the underlying secret.
By leveraging these principles, our authentication vault eliminates the traditional attack surface. There are no password hashes sitting in a remote database waiting to be cracked via offline brute-force attacks. There is simply a dynamic mathematical handshake that validates identity in real time, leaving zero cryptographic residue behind.
Architecting the Sovereign Vault: Core Principles and Component Design
Building a custom vault requires ruthless minimalism. Every added feature, every third-party software dependency, and every convenience utility expands the potential attack surface. When designing a system focused on verifiable compute and absolute data privacy, the software architecture must be stripped down to its essential components: local storage, deterministic key derivation, strict memory sanitization, and localized verification routines.
The foundation of the architecture begins with local-first persistence. The vault database does not live on AWS, Google Cloud, or a synced commercial directory. It lives on local, encrypted block storage controlled directly by the operating system user permissions of the host machine. The database file itself is protected using authenticated encryption with associated data (AEAD), ensuring that any unauthorized attempt to modify or tamper with the ciphertext is detected immediately upon decryption.
Key management within this sovereign environment eschews simple passwords in favor of multi-factor hardware tokens and localized biometric integration backed by hardware security modules (HSMs) or Trusted Platform Modules (TPMs). When the vault is unlocked, the decryption keys exist solely within volatile system RAM for the shortest possible duration, stripped from memory buffers immediately after the requested credential is retrieved and injected.
Reviewing the structural requirements of a sovereign security vault clarifies the engineering priorities:
- Local-First Storage: Data remains strictly on user-controlled hardware, preventing cloud-based metadata harvesting.
- Memory Hygiene: Sensitive plaintext strings are explicitly zeroed out of RAM buffers as soon as their operation completes.
- Verifiable Cryptographic Primitives: Relying exclusively on peer-reviewed, open-source cryptographic libraries rather than proprietary or custom-built algorithms.
- Air-Gapped Sync Options: Allowing device-to-device synchronization via encrypted peer-to-peer tunnels rather than mandatory centralized relay servers.
- Deterministic Recovery: Using industry-standard mnemonic seed phrases to ensure deterministic recovery without relying on third-party password reset flows.
This blueprint shifts the burden of security from corporate policy compliance to hard mathematical guarantees. It creates an ecosystem where your credentials are yours alone, protected by physics and mathematics rather than corporate terms of service.
Step-by-Step Implementation Strategy for Your Personal Vault
Transitioning from a consumer cloud password manager to a custom-built, sovereign verification architecture requires a methodical, disciplined approach. You cannot simply flip a switch; you must migrate your digital identity with surgical precision, ensuring that no data is left behind and that your operational security remains uncompromised throughout the process.
The first phase of implementation involves auditing your existing digital footprint. Export your current password database from your legacy provider into an unencrypted intermediary format only within a securely isolated, offline environment—ideally an air-gapped machine or a temporary volatile RAM disk. Once exported, parse the raw data to remove outdated accounts, legacy credentials, and redundant entries. A migration is the ideal time to ruthlessly prune your digital attack surface.
The second phase focuses on setting up your local vault environment. Initialize your chosen open-source cryptographic engine, generate a high-entropy master mnemonic seed phrase, and store physical backups of that seed on durable, fireproof media away from any internet-connected device. Configure your local storage parameters, establish your key derivation parameters with maximum computational iterations, and verify that your local encryption keys successfully bind to your hardware security token.
The final phase involves importing and verifying your credentials. Map your parsed data into the localized database structure, ensuring that metadata fields are stripped or heavily obfuscated. Test your authentication loops across your primary and secondary devices using local, peer-to-peer sync mechanisms or encrypted manual file transfers. Once you have confirmed that your vault operates smoothly, securely wipe the intermediary export files using secure deletion protocols that overwrite disk sectors multiple times.
Throughout this migration, remember that operational security is a continuous practice, not a one-time project. Regularly audit your vault logs, verify your backup integrity, and ensure your local software dependencies remain updated through verified open-source channels.
Securing Your Digital Future Without Compromise
Stepping away from the comfort of Big Tech infrastructure requires a willingness to embrace personal responsibility. When you stop trusting centralized corporations with your secrets, you reclaim the fundamental sovereignty that the early internet promised: absolute ownership of your digital identity, unmediated by landlords, advertisers, or cloud gatekeepers.
Building and utilizing a zero knowledge password vault proves that absolute privacy and robust digital authentication are not mutually exclusive. By anchoring your security in mathematical proofs, local-first storage, and zero-knowledge protocols, you render yourself immune to cloud data breaches, telemetry harvesting, and third-party coercion. Your keys remain yours, your secrets remain silent, and your digital footprint remains entirely under your control.
What are the primary implementation requirements for getting started?
You need standard baseline computing resources, open-source orchestration tooling, and adherence to security microsegmentation. Full step-by-step configurations are detailed in the implementation section above.
How does this paradigm scale in production environments?
Because the system avoids centralized bottlenecks and relies on edge autonomy, performance scales linearly with minimal compute overhead and zero recurring license fees.
What are the primary implementation requirements for getting started?
You need standard baseline computing resources, open-source orchestration tooling, and adherence to security microsegmentation. Full step-by-step configurations are detailed in the implementation section above.
How does this paradigm scale in production environments?
Because the system avoids centralized bottlenecks and relies on edge autonomy, performance scales linearly with minimal compute overhead and zero recurring license fees.