Architecting Adaptive Just-In-Time Compilers in 2026: Real-Time eBPF Instruction Tracing, Polyhedral Loop Vectorization via MLIR, and Zero-Stall On-Stack Replacement Pipelines
Key Takeaways
- Adaptive JITs use eBPF/PMU for non-invasive, low-overhead performance tracing, replacing intrusive software profiling.
- MLIR enables polyhedral transformations for advanced vectorization and optimization of hot loops.
- Zero-stall OSR asynchronously converts interpreter frames to native, preventing performance interruptions.
- These JITs deliver deterministic performance for high-throughput, low-latency distributed microservices and inference.
- Modern JITs combine eBPF tracing, MLIR polyhedral optimization, and zero-stall OSR for adaptive performance.
Modern Just-In-Time (JIT) compilation architectures are undergoing a fundamental paradigm shift away from intrusive, counter-based software profiling toward out-of-band hardware telemetry and multi-level polyhedral intermediate representations. By combining real-time Linux Extended Berkeley Packet Filter (eBPF) instruction-level tracing with the Multi-Level Intermediate Representation (MLIR) framework, modern runtime environments can dynamically optimize compute-heavy kernels without introducing latency spikes or execution stalls. When paired with zero-stall On-Stack Replacement (OSR) pipelines built using memory-safe systems languages, these adaptive compilers deliver deterministic performance for high-throughput distributed microservices, financial matching engines, and real-time inference workloads.
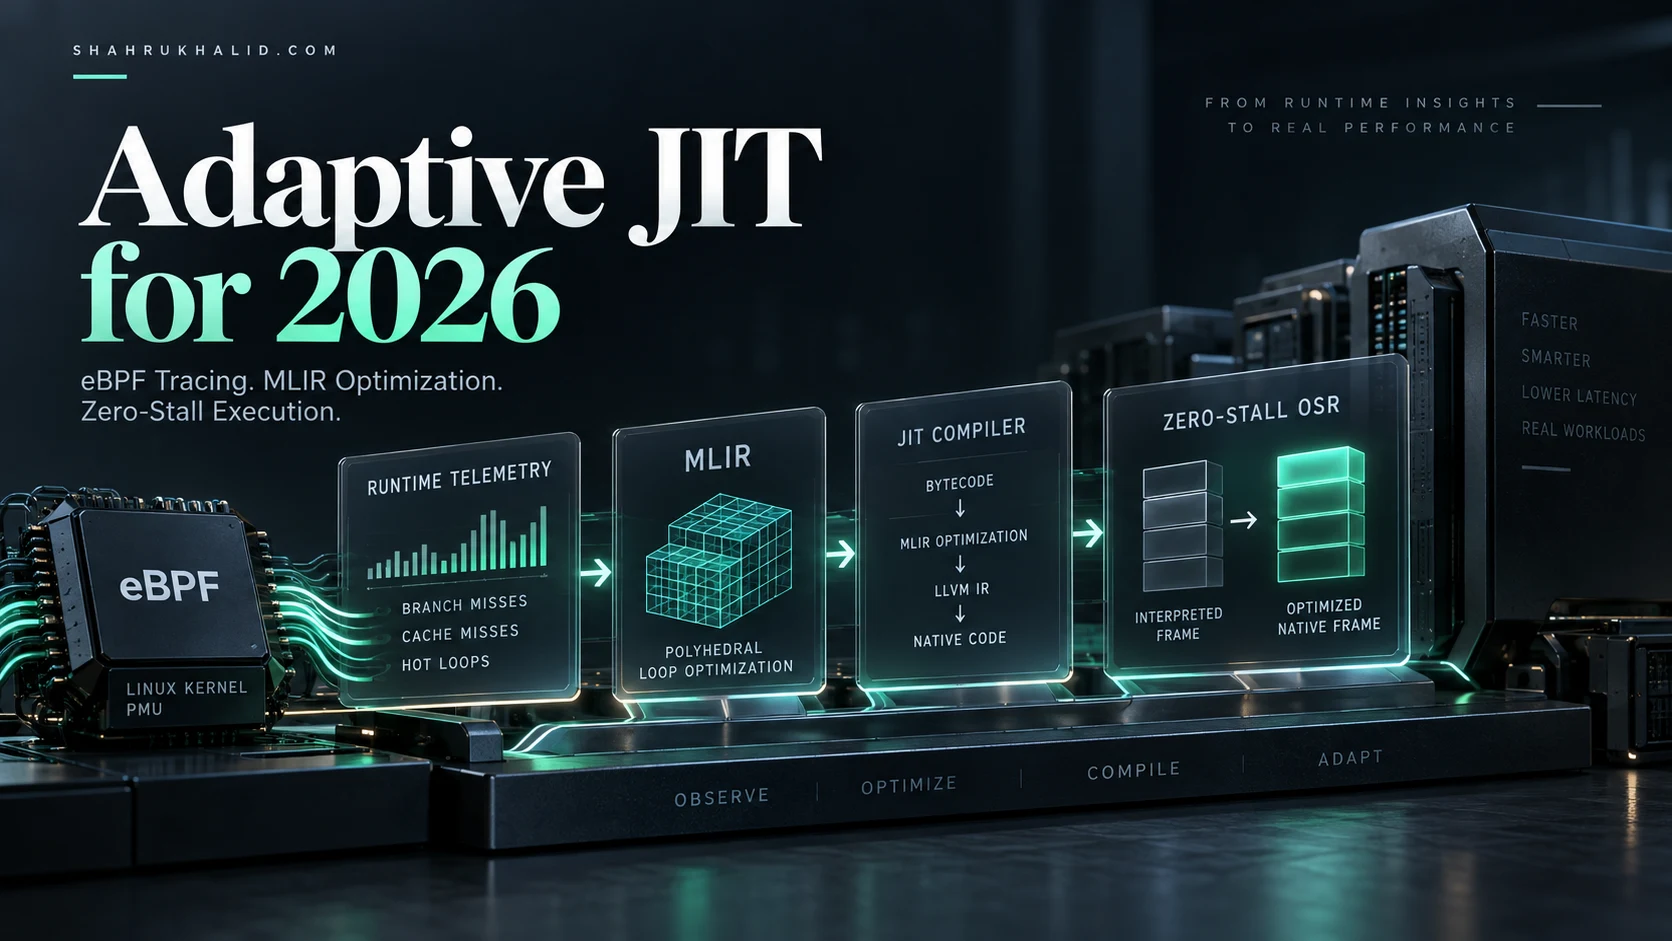
High-Level Adaptive JIT Compilation Architecture
eBPF + Linux PMU hooks trace branch mispredictions, cache misses, and hot loop trip counts directly from kernel space without code instrumentation.
Hot bytecodes lowered to MLIR Affine/SCF dialects. Polyhedral transformations perform tiling, skewing, and AVX-512/ARM SVE vectorization.
MLIR lowers to LLVM IR, generating position-independent machine code into dual-mapped, PKU-protected executable memory pages.
Active interpreter stack frames are converted to optimized native stack layouts asynchronously at deopt/safepoint boundaries without thread suspension.
The Paradigm Shift: Non-Invasive eBPF Telemetry vs. Intrusive Software Profiling
Traditional Tier-1 JIT compilers (such as HotSpot C1 or V8 Sparkplug/Maglev) rely on software-managed profiling counters injected directly into the execution path. Interpreters and baseline compilers increment invocation counters at method entries and loop back-edges:
// Traditional runtime overhead: Intrusive back-edge counter
void interpret_loop_backedge(Method* m, Frame* frame) {
    if (++m->backedge_counter > TIER1_THRESHOLD) {
        trigger_background_compilation(m, frame);
    }
}
This approach has three major structural defects when applied to modern low-latency runtimes:
- L1 Cache Line Invalidation: Constantly updating software invocation counters introduces cache coherency traffic and causes pipeline stalls across concurrent execution threads.
- Heuristic Inaccuracy: Simple invocation counters do not measure memory latency, CPU pipeline stalls, cache misses, or data alignment hazards.
- Code Bloat: Emitting profiling hooks throughout the generated bytecode inflates the instruction cache footprint, increasing instruction TLB (iTLB) misses.
Kernel-Level Tracing with eBPF and Hardware PMUs
Modern runtimes offload performance tracing to the Linux kernel via eBPF. By attaching eBPF programs to Performance Monitoring Unit (PMU) hardware counters (such as PERF_COUNT_HW_CPU_CYCLES, PERF_COUNT_HW_CACHE_MISSES, and PERF_COUNT_HW_BRANCH_MISSES) using BPF_PROG_TYPE_PERF_EVENT, we can trace execution hot spots with near-zero overhead (<0.5% CPU overhead).
The following eBPF C program inspects user-space Instruction Pointers (IPs) directly, mapping physical execution addresses to runtime method structures via a concurrent BPF hash map:
// ebpf_trace.bpf.c
#include <linux/bpf.h>
#include <linux/ptrace.h>
#include <bpf/bpf_helpers.h>
#include <bpf/bpf_tracing.h>

struct method_hotspot_key {
    __u64 ip;
    __u32 pid;
    __u32 method_id;
};

struct hotspot_metrics {
    __u64 execution_samples;
    __u64 l1_dcache_misses;
    __u64 branch_mispredictions;
};

struct {
    __uint(type, BPF_MAP_TYPE_HASH);
    __uint(max_entries, 65536);
    __type(key, struct method_hotspot_key);
    __type(value, struct hotspot_metrics);
} jit_hotspots SEC(".maps");

struct {
    __uint(type, BPF_MAP_TYPE_RINGBUF);
    __uint(max_entries, 1024 * 1024);
} tiering_events SEC(".maps");

SEC("perf_event")
int trace_jit_hotspot(struct bpf_perf_event_data *ctx) {
    struct method_hotspot_key key = {};
    key.pid = bpf_get_current_pid_tgid() >> 32;
    key.ip = ctx->regs.ip;

    struct hotspot_metrics *metrics = bpf_map_lookup_elem(&jit_hotspots, &key);
    if (!metrics) {
        struct hotspot_metrics initial = { .execution_samples = 1 };
        bpf_map_update_elem(&jit_hotspots, &key, &initial, BPF_NOEXIST);
        return 0;
    }

    __sync_fetch_and_add(&metrics->execution_samples, 1);

    // Trigger high-tier compilation if sample threshold exceeds limit
    if (metrics->execution_samples >= 5000) {
        struct method_hotspot_key *event = bpf_ringbuf_reserve(&tiering_events, sizeof(key), 0);
        if (event) {
            *event = key;
            bpf_ringbuf_submit(event, 0);
        }
        // Reset count to prevent spamming compiler queues
        metrics->execution_samples = 0;
    }

    return 0;
}

char LICENSE[] SEC("license") = "GPL";
MLIR Polyhedral Pipeline: From Bytecode to Affine Dialect Vectorization
Traditional JIT compilers (such as LLVM ORC or Java HotSpot C2) use Sea-of-Nodes or basic Control Flow Graph (CFG) representations. These low-level abstractions lose the structural multidimensional loop geometry required to optimize high-performance numeric kernels, matrix operations, and tensor transformations.
The Multi-Level Intermediate Representation (MLIR) framework addresses this limitation. By compiling hot bytecodes into MLIR’s Affine Dialect, loops are treated as mathematical polyhedra. We represent the iteration domain as a system of linear inequalities:
$$mathcal{D} = { vec{i} in mathbb{Z}^n mid mathbf{A}vec{i} + vec{b} ge vec{0} }$$
1. Bytecode Ingestion
Interpreted bytecode extracted from hot frames is validated and translated into the high-level MLIR func and memref dialects.
2. Affine Lowering
Loops are mapped into affine.for constructs with explicit iteration domains and access functions, exposing polyhedral dependency relations.
3. Polyhedral Passes
Affine dialect passes perform polyhedral loop skewing, hierarchical cache tiling, loop fusion, and unroll-and-jam operations.
4. Vector Dialect Lowering
Optimized affine loops lower to the vector dialect, targeting hardware SIMD intrinsics (AVX-512, ARM SVE2, or RISC-V Vector).
MLIR Polyhedral Loop Lowering Example
The following MLIR module demonstrates the transform pipeline: a multidimensional numeric loop is lifted into the affine dialect, tiled for cache locality, and lowered directly to target-specific vector registers.
// MLIR Module: Hot Matrix Multiplication Lowered to Polyhedral Representation
module @jit_adaptive_kernel {
  func.func @matmul_affine(
    %A: memref<1024x1024xf32>,
    %B: memref<1024x1024xf32>,
    %C: memref<1024x1024xf32>
  ) {
    // Affine loop nest enabling polyhedral dependency analysis
    affine.for %i = 0 to 1024 step 32 {
      affine.for %j = 0 to 1024 step 32 {
        affine.for %k = 0 to 1024 step 32 {
          // Inner tiled iteration block
          affine.for %ii = affine_map<(d0) -> (d0)>(%i) to affine_map<(d0) -> (d0 + 32)>(%i) {
            affine.for %jj = affine_map<(d0) -> (d0)>(%j) to affine_map<(d0) -> (d0 + 32)>(%j) step 8 {
              affine.for %kk = affine_map<(d0) -> (d0)>(%k) to affine_map<(d0) -> (d0 + 32)>(%k) {
                // Load 8 contiguous floats using SIMD vector load
                %vec_b = vector.transfer_read %B[%kk, %jj], %c0 : memref<1024x1024xf32>, vector<8xf32>
                %scalar_a = affine.load %A[%ii, %kk] : memref<1024x1024xf32>
                %vec_a = vector.broadcast %scalar_a : f32 to vector<8xf32>

                %vec_c_in = vector.transfer_read %C[%ii, %jj], %c0 : memref<1024x1024xf32>, vector<8xf32>

                // Fused Multiply-Add (FMA) operation
                %vec_c_out = vector.fma %vec_a, %vec_b, %vec_c_in : vector<8xf32>

                vector.transfer_write %vec_c_out, %C[%ii, %jj] : vector<8xf32>, memref<1024x1024xf32>
              }
            }
          }
        }
      }
    }
    return
  }
}
Zero-Stall On-Stack Replacement (OSR) & Deoptimization Mechanics
One of the hardest challenges in adaptive compilation is On-Stack Replacement (OSR): upgrading an active, interpreting stack frame to a newly compiled, highly optimized Tier-2 machine code frame without stalling the running thread or waiting for the method to return.
Zero-Stall OSR Frame Transformation
Interpreted Frame (Tier-0)
[Dynamic Local Array Ptr]
[Bytecode Program Counter]
[Virtual Register Map]
[Operand Stack Array]
OSR Transition Stub
[Translate Register Alloc]
[Patch Base Pointer (RBP)]
[Adjust Stack Bounds]
Optimized Native Frame (Tier-2)
[Spill Slot: Vector %ymm0]
[Spill Slot: Vector %ymm1]
[Pinned GPRs: %r12-%r15]
[Safepoint Invalidation Bit]
Asynchronous Stack Reconstruction in Rust
To eliminate execution stalls, the runtime must avoid stopping the world during compilation. Instead, the runtime places an asynchronous compilation request into a channel and continues executing the baseline interpreter. Once the polyhedral MLIR pipeline generates the target code, it compiles an OSR Transition Trampoline.
When the interpreter reaches a loop back-edge safepoint, it checks an atomic pointer. If the Tier-2 entry address is populated, it transfers execution by reconstructing the frame dynamically in place:
// osr_engine.rs
use std::sync::atomic::{AtomicPtr, Ordering};
use std::alloc::{alloc, Layout};

#[repr(C)]
pub struct InterpreterFrame {
    pub return_address: usize,
    pub bytecode_pc: usize,
    pub locals_count: usize,
    pub locals: *mut u64,
}

#[repr(C)]
pub struct NativeTier2Entry {
    pub code_ptr: extern "C" fn(*const u64) -> u64,
    pub frame_size: usize,
    pub register_map: *const u8,
}

pub struct MethodMetadata {
    pub method_id: u32,
    pub tier2_entry: AtomicPtr,
}

impl MethodMetadata {
    /// Zero-overhead polling hook invoked at loop back-edges
    #[inline(always)]
    pub unsafe fn poll_osr_entry(&self, current_frame: &mut InterpreterFrame) -> Option<u64> {
        let entry_ptr = self.tier2_entry.load(Ordering::Acquire);
        if entry_ptr.is_null() {
            return None; // Fast-path: remain in interpreter
        }

        let entry = &*entry_ptr;
        Some(self.execute_osr_transition(current_frame, entry))
    }

    #[inline(never)]
    unsafe fn execute_osr_transition(
        &self,
        frame: &InterpreterFrame,
        entry: &NativeTier2Entry,
    ) -> u64 {
        // Collect live variables defined by the interpreter frame
        let local_slice = std::slice::from_raw_parts(frame.locals, frame.locals_count);

        // Execute the Tier-2 optimized code via the trampoline
        (entry.code_ptr)(local_slice.as_ptr())
    }
}
High-Performance API Design: Low-Latency Runtime Integration in Rust and Go
High-performance systems programming requires robust concurrency models and deterministic memory safety. Building JIT compilation pipelines requires balancing thread safety, zero-copy I/O, and low latency across both Rust’s memory-safe, fearless concurrency model and Go’s concurrent, zero-allocation runtime patterns.
Language-Specific Integration Architecture
High-Throughput Ingestion Engine in Go
The following production Go service consumes hot-spot notifications from the eBPF kernel ring buffer, manages allocation pools to avoid runtime GC overhead, and dispatches compilation jobs to an external native compilation worker:
// telemetry_consumer.go
package main

import (
	"context"
	"errors"
	"fmt"
	"log"
	"os"
	"sync"
	"unsafe"

	"github.com/cilium/ebpf/ringbuf"
)

type HotspotEvent struct {
	IP       uint64
	PID      uint32
	MethodID uint32
}

type TelemetryConsumer struct {
	reader    *ringbuf.Reader
	eventPool sync.Pool
	jobQueue  chan HotspotEvent
}

func NewTelemetryConsumer(rd *ringbuf.Reader, queueSize int) *TelemetryConsumer {
	return &TelemetryConsumer{
		reader: rd,
		eventPool: sync.Pool{
			New: func() any {
				return new(HotspotEvent)
			},
		},
		jobQueue: make(chan HotspotEvent, queueSize),
	}
}

func (tc *TelemetryConsumer) Start(ctx context.Context, workers int) {
	for range workers {
		go tc.compilationWorker(ctx)
	}

	go func() {
		for {
			select {
			case <-ctx.Done():
				return
			default:
				record, err := tc.reader.Read()
				if err != nil {
					if errors.Is(err, ringbuf.ErrClosed) {
						return
					}
					continue
				}

				if len(record.RawSample) < int(unsafe.Sizeof(HotspotEvent{})) {
					continue
				}

				event := (*HotspotEvent)(unsafe.Pointer(&record.RawSample[0]))

				// Non-blocking channel dispatch
				select {
				case tc.jobQueue <- *event:
				default:
					// Compilation queue saturated: drop telemetry frame to preserve throughput
				}
			}
		}
	}()
}

func (tc *TelemetryConsumer) compilationWorker(ctx context.Context) {
	for {
		select {
		case <-ctx.Done():
			return
		case job := <-tc.jobQueue:
			// Dispatch to native MLIR/LLVM tiering engine via IPC or C-Shared bindings
			tc.processHotspot(job)
		}
	}
}

func (tc *TelemetryConsumer) processHotspot(event HotspotEvent) {
	// Ingestion pipeline logic: Invokes JIT Compiler Tiering Service
	log.Printf("[JIT Telemetry] Method %d reached threshold at IP 0x%X", event.MethodID, event.IP)
}
Dual-Mapped Executable Memory Management in Rust
Modern operating systems enforce strict W^X (Write XOR Execute) memory security policies. To allow a multi-threaded compiler to generate and write machine code concurrently while the execution engine runs, the code cache must use dual-mapped virtual memory via memfd_create:
// code_cache.rs
use std::os::unix::io::AsRawFd;
use nix::sys::memfd::{memfd_create, MemFdCreateFlag};
use nix::sys::mman::{mmap, MapFlags, ProtFlags};
use std::num::NonZeroUsize;
use std::ptr::NonNull;

pub struct DualMappedCodeCache {
    write_ptr: NonNull<u8>,
    exec_ptr: NonNull<u8>,
    capacity: usize,
}

unsafe impl Send for DualMappedCodeCache {}
unsafe impl Sync for DualMappedCodeCache {}

impl DualMappedCodeCache {
    pub fn new(capacity: usize) -> Result<Self, Box<dyn std::error::Error>> {
        let fd = memfd_create(
            c"jit_code_cache",
            MemFdCreateFlag::MFD_CLOEXEC | MemFdCreateFlag::MFD_ALLOW_SEALING,
        )?;

        nix::unistd::ftruncate(fd.as_raw_fd(), capacity as i64)?;

        // Writable alias (no execute permission)
        let write_addr = unsafe {
            mmap(
                None,
                NonZeroUsize::new(capacity).unwrap(),
                ProtFlags::PROT_READ | ProtFlags::PROT_WRITE,
                MapFlags::MAP_SHARED,
                fd.as_raw_fd(),
                0,
            )?
        };

        // Executable alias (no write permission)
        let exec_addr = unsafe {
            mmap(
                None,
                NonZeroUsize::new(capacity).unwrap(),
                ProtFlags::PROT_READ | ProtFlags::PROT_EXEC,
                MapFlags::MAP_SHARED,
                fd.as_raw_fd(),
                0,
            )?
        };

        Ok(Self {
            write_ptr: NonNull::new(write_addr.as_ptr() as *mut u8).unwrap(),
            exec_ptr: NonNull::new(exec_addr.as_ptr() as *mut u8).unwrap(),
            capacity,
        })
    }

    /// Emits code to the writable view; returns the executable pointer for execution
    pub unsafe fn emit_code(&self, offset: usize, machine_code: &[u8]) -> Result<*const u8, &'static str> {
        if offset + machine_code.len() > self.capacity {
            return Err("Code cache capacity exceeded");
        }

        // Copy into writable view
        let dest = self.write_ptr.as_ptr().add(offset);
        std::ptr::copy_nonoverlapping(machine_code.as_ptr(), dest, machine_code.len());

        // Return execution pointer located at identical offset
        Ok(self.exec_ptr.as_ptr().add(offset) as *const u8)
    }
}
Architectural Comparison: Legacy JIT vs. Adaptive 2026 Telemetry-Driven JIT
To quantify the technical trade-offs of this architecture, the following table compares legacy tracing and method JIT compilers against the eBPF + MLIR + Zero-Stall OSR pattern:
Summary Architecture & Implementation Checklist
When architecting a production-grade adaptive JIT compiler in 2026, adhere to the following core systems-level principles:
- Decouple Telemetry from Execution: Eliminate inlined software invocation counters. Rely exclusively on kernel eBPF sampling connected to CPU hardware performance counters via perf ring buffers.
- Leverage Polyhedral Loop Transformations: Lower dynamic hot spots to MLIR
affineandvectordialects instead of flat control flow graphs to unlock SIMD vectorization across AVX-512 and ARM SVE2 targets. - Design for Zero-Stall OSR Transitions: Compile non-blocking OSR transition trampolines asynchronously. Reconstruct stack frames at predictable loop back-edge safepoints without triggering global Stop-The-World pauses.
- Enforce Strict W^X Compliant Memory Safety: Use dual-mapped memory spaces via
memfd_create. Ensure the execution engine cannot access writable descriptors, and compilation threads cannot directly execute code memory. - Apply High-Performance Concurrency Patterns: Use Go and Rust API designs that prioritize zero-allocation data ingestion, explicit epoch-based memory reclamation, and thread-safe lock-free channels.