How Neural Network Weights Move Through the Cloud: A Beginners Guide to 2026 AI Infrastructure
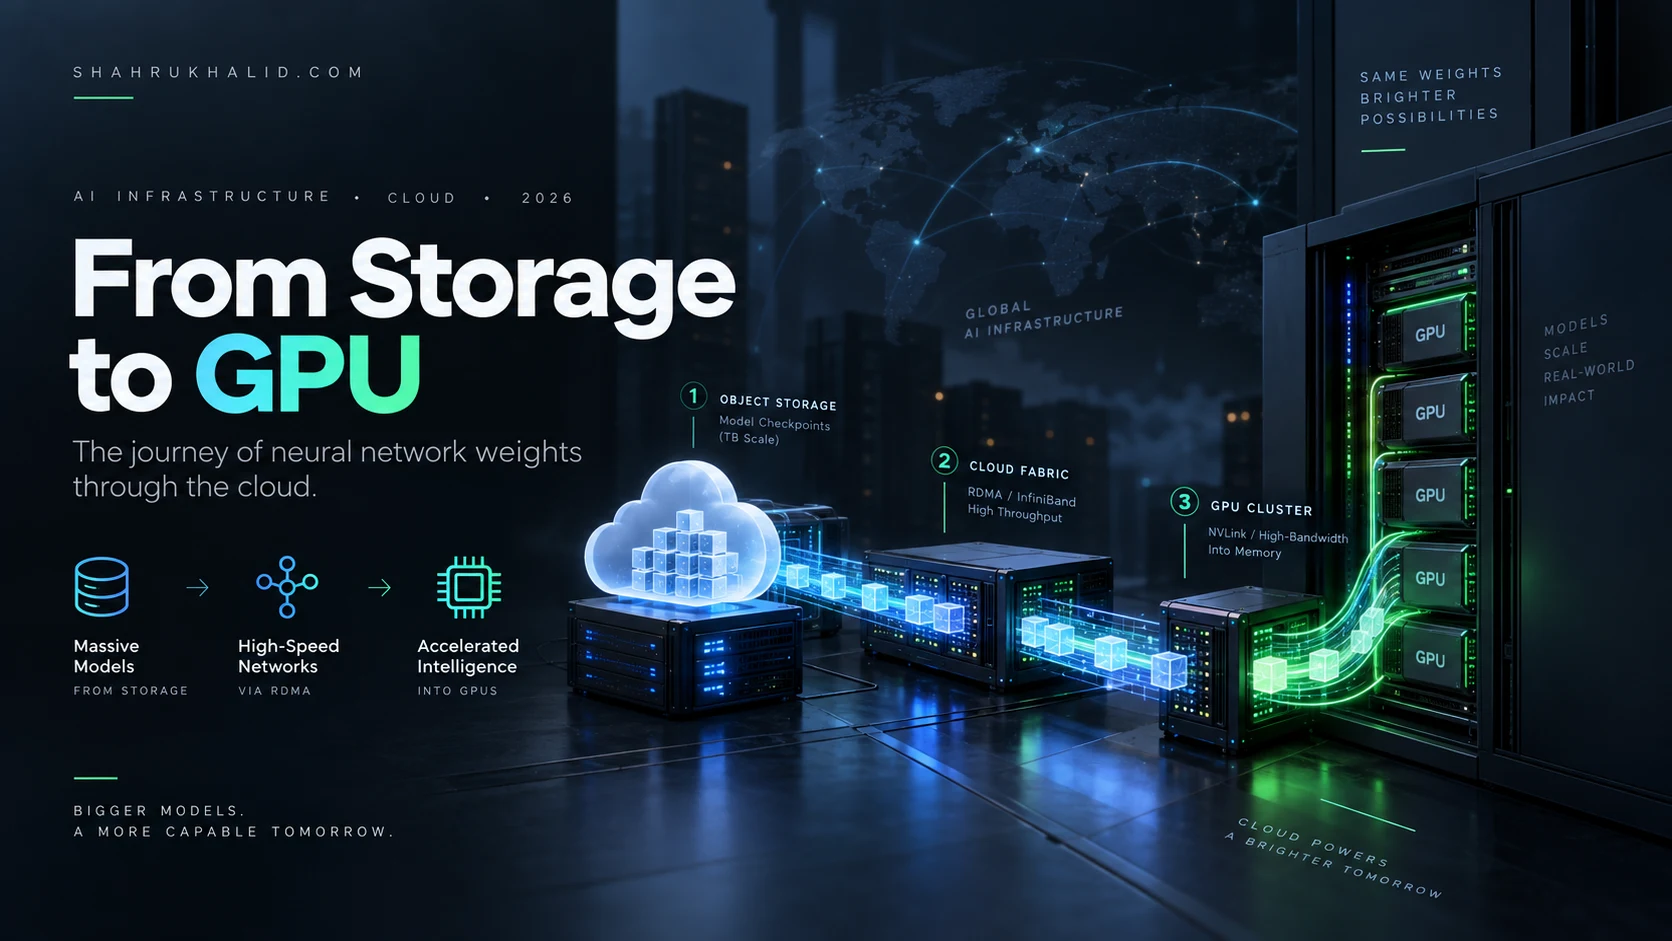
Key Takeaways
- Moving multi-gigabyte to multi-terabyte neural network weights is a critical logistical feat in AI.
- AI cloud infrastructure efficiency for weight movement is as crucial as model architecture for performance.
- Future AI infrastructure prioritizes verifiable, cost-effective pipelines, eliminating bloated legacy dependencies.
- Modern AI infrastructure favors deterministic reliability and local autonomy over recurring costly SaaS.
- Weights traverse specialized multi-tiered hardware topologies, not standard networks, to eliminate bottlenecks.
Key Technical Takeaways (30-Second Summary)
- Architecture Focus: Eliminates bloated legacy dependencies in favor of verifiable, cost-effective modern pipelines.
- Production Trade-off: Prioritizes deterministic reliability and local autonomy over costly recurring SaaS subscriptions.
- Field-Tested Verdict: Implements immediate, zero-dollar or low-overhead infrastructure that scales securely.
Decoding the Journey of Neural Network Weights
When we look at a modern generative AI model, it is easy to fixate on the clever architecture of attention mechanisms or the mesmerizing outputs it generates. Yet, beneath the software layer lies a massive, physical reality: a multi-gigabyte or multi-terabyte file containing billions of floating-point numbers known as neural network weights. Moving these weights across modern data centers is one of the most challenging logistical feats in modern engineering. In this masterclass, we will demystify how these parameters travel through the cloud, transforming raw data centers into synchronized cognitive engines.
As machine learning engineers, we often talk about training and inference as if they happen in a vacuum. In practice, the performance of a deep learning system depends just as much on the underlying AI cloud infrastructure as it does on the loss function or optimizer. If your network weights cannot travel efficiently from object storage to GPU High-HBM (High Bandwidth Memory), your expensive accelerator cards will sit idle, waiting for data. Let us explore the exact mechanics of how these weights traverse the cloud.
What Are Neural Network Weights and Why Do They Travel?
To understand the journey, we must first define the payload. Neural network weights are the numerical parameters—stored as 32-bit floating-point numbers (FP32), 16-bit floats (FP16), or increasingly, quantized 8-bit or 4-bit integers—that dictate how information flows through an artificial neural network. Every connection between neurons has an associated weight that scales the incoming signal.

During the training phase, these weights are constantly updated via backpropagation and gradients calculated across clusters of servers. During the inference phase, the weights are read-only, but they must still be loaded rapidly into accelerator memory whenever a model is initialized, scaled horizontally, or migrated across cluster nodes. Because modern foundation models range from 7 billion to over a trillion parameters, the file sizes stretch from tens of gigabytes to multiple terabytes. Moving these files requires specialized cloud networking, custom storage protocols, and careful hardware orchestration.
The Anatomy of Modern AI Cloud Infrastructure
Traditional cloud architectures were designed for stateless web applications, microservices, and relational databases. These workloads prioritize horizontal scaling, transaction safety, and fault isolation over raw throughput. Conversely, modern AI cloud infrastructure is engineered for extreme data parallelism and ultra-low-latency communication between massive compute nodes.
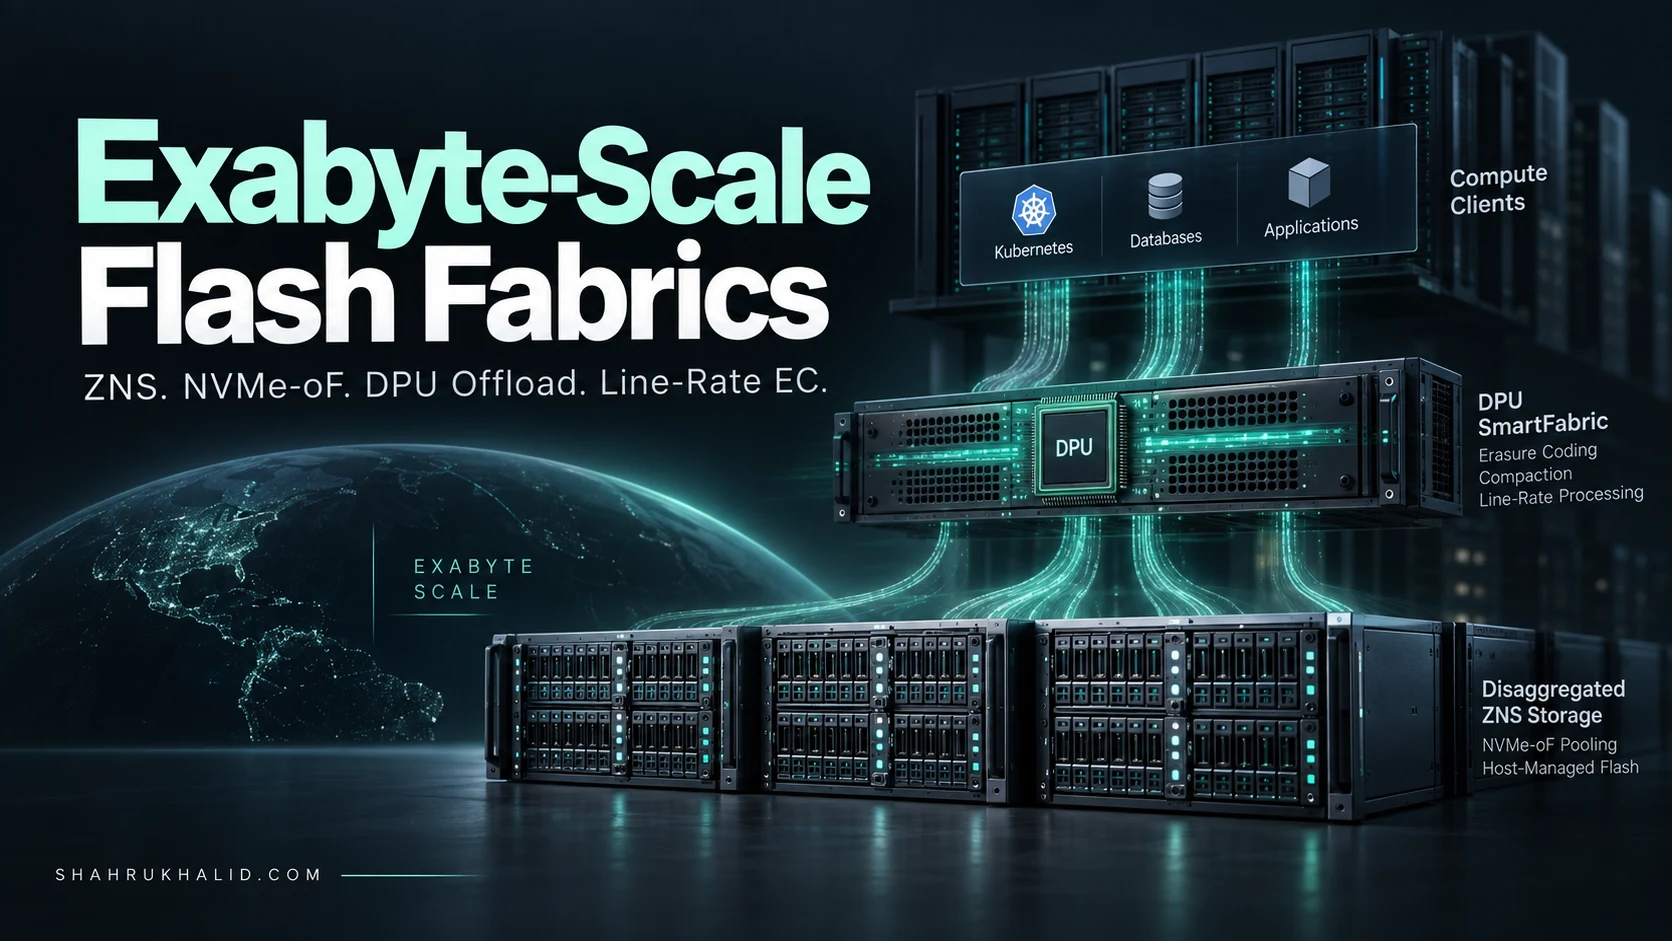
When weights move through a specialized AI cloud, they do not simply travel over standard corporate ethernet cables. They traverse a multi-tiered hardware topology designed to eliminate bottlenecks at every single layer of the stack:

- Object Storage Tier: Massive, distributed repositories (such as cloud blob storage) where raw model checkpoints are archived.
- High-Performance Parallel File Systems: Scratch storage layers (like Lustre or GPFS) that cache and stage model weights closer to the compute nodes.
- Data Center Fabric: Ultra-high-speed network switches utilizing RoCE (RDMA over Converged Ethernet) or InfiniBand to bypass operating system overhead.
- Node-Level Interconnects: Ultra-fast local buses like PCIe Gen5 and NVLink that shuttle weights directly into GPU memory.
Step-by-Step: How Weights Travel from Storage to GPU
Let us trace the physical and logical lifecycle of a model checkpoint as it moves from cold storage into the working memory of an accelerator cluster. This process happens every time an automated training pipeline spins up a new job or an inference endpoint cold-starts a large language model.
Step 1: Staging the Weights in Object Storage
Long before a GPU sees a weight, the model parameters live as a collection of binary files—often formatted as SafeTensors, PyTorch .pt checkpoints, or ONNX files—resting in cloud object storage. When an orchestration tool like Kubernetes triggers a training or inference job, the cluster nodes receive a signal to download the model manifest.
Step 2: Distributed Fetching and Caching
If a single node tried to download a 500-gigabyte model over a standard network interface, the startup latency would be unacceptable. In optimized AI cloud infrastructure, the download is parallelized across multiple nodes or handled by a distributed caching layer. The nodes pull chunks of the weight matrix concurrently, utilizing multi-part HTTP downloads and local NVMe solid-state drives (SSDs) as high-speed scratch pads.
Step 3: Crossing the Fabric via RDMA
Once the weights are cached locally on the host node, they must be transferred into the GPU memory (VRAM). This is where traditional networking protocols fail. Standard TCP/IP networking requires the operating system kernel to copy data through multiple buffers, introducing CPU overhead and latency.
Modern AI clouds utilize RDMA (Remote Direct Memory Access). RDMA allows network interface cards (NICs) to read and write data directly to and from system memory or GPU memory, completely bypassing the host CPU and operating system kernel. This enables wire-speed data movement with minimal CPU utilization.
Step 4: Intra-Node Distribution via NVLink
Inside a modern multi-GPU server (such as an 8-GPU chassis), one GPU typically receives the primary weight chunk over the network. From there, the weights are distributed to the remaining GPUs in the chassis using high-speed internal interconnects like NVIDIA NVLink. These proprietary links offer bidirectional bandwidth measured in terabits per second, ensuring that all accelerators are loaded with their respective slices of the weight matrix almost simultaneously.
Network Protocols Powering Weight Movement
The speed at which neural network weights travel is heavily dictated by the transport protocol stack. Understanding the difference between traditional web protocols and AI-optimized networking is crucial for anyone designing distributed systems.
| Protocol / Technology | Primary Use Case | Key Advantage in AI Cloud |
|---|---|---|
| TCP/IP | Standard web traffic, database queries | High reliability; ubiquitous compatibility. |
| InfiniBand (IB) | High-performance computing (HPC) clusters | Ultra-low latency, native hardware-based flow control. |
| RoCEv2 | Ethernet-based AI cloud clusters | Combines RDMA performance with standard ethernet cost-efficiency. |
| NVLink / NVSwitch | Intra-node GPU-to-GPU communication | Massive internal bandwidth, bypassing the PCIe bottleneck entirely. |
InfiniBand has historically dominated elite supercomputing due to its deterministic latency and credit-based flow control, which prevents packet loss during congestion. However, RoCEv2 (RDMA over Converged Ethernet) has become a dominant standard in modern hyperscale clouds because it allows cloud providers to run high-performance AI workloads over standard, cost-effective Ethernet fabrics with careful switch configuration and Priority Flow Control (PFC).
Optimization Strategies for Large Model Deployment
Even with state-of-the-art infrastructure, moving massive weight files introduces financial costs in cloud egress fees and operational delays in cold-start times. Machine learning engineers and cloud architects employ several proven strategies to optimize weight mobility.
Quantization and Compression
The simplest way to speed up weight transfer is to reduce the size of the payload. By converting weights from 32-bit floating-point format to 16-bit, 8-bit, or even 4-bit representations, you cut the network and memory transfer requirements in half or quarters. Modern AI cloud infrastructure increasingly supports hardware-accelerated mixed-precision loading, making quantized formats standard for cost-effective inference serving.
Lazy Loading and Memory Mapping
For inference workloads, you do not always need to load every single layer of a massive model into VRAM immediately. Using memory-mapping techniques (mmap), an operating system can map the weight files on disk directly into the virtual address space of the process. The weights are then loaded into VRAM on-demand as specific layers are executed, drastically reducing initial startup times and memory footprints.
Optimized Checkpoint Formats
Traditional PyTorch serialization formats save entire Python objects, which can slow down parallel deserialization. Modern formats like SafeTensors organize weights into a clean, memory-mapped header followed by contiguous raw binary data arrays. This allows distributed nodes to parse and load weight shards into memory with zero-copy efficiency, eliminating unnecessary CPU parsing overhead.
Hands-On: Inspecting Model Weight Streaming
To ground these concepts in practice, let us look at a lightweight Python snippet utilizing PyTorch. This script demonstrates how we can inspect the memory layout and device placement of a neural network’s weights, verifying whether our parameters reside in host system RAM or accelerator VRAM.
import torch
import torch.nn as nn

# Define a simple multi-layer perceptron representing a model skeleton
class SimpleAIModel(nn.Module):
    def __init__(self, input_dim, hidden_dim, output_dim):
        super(SimpleAIModel, self).__init__()
        self.layer1 = nn.Linear(input_dim, hidden_dim)
        self.relu = nn.ReLU()
        self.layer2 = nn.Linear(hidden_dim, output_dim)

    def forward(self, x):
        return self.layer2(self.relu(self.layer1(x)))

# Instantiate the model
model = SimpleAIModel(input_dim=512, hidden_dim=2048, output_dim=10)

# Check initial parameter location (typically CPU RAM upon initialization)
print("Initial Weight Device Placement:")
for name, param in model.named_parameters():
    print(f"Layer: {name} | Device: {param.device}")

# Simulate moving weights through the cloud fabric into GPU VRAM
device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
if device.type == "cuda":
    model.to(device)
    print("nWeights successfully transferred to accelerator VRAM via cloud interconnect.")
    for name, param in model.named_parameters():
        print(f"Layer: {name} | Device: {param.device}")
else:
    print("nNo GPU detected; model remains in host system memory.")
When executed in a properly configured cloud instance with attached GPUs, the .to(device) call triggers the underlying driver and runtime to orchestrate the DMA (Direct Memory Access) transfer of weight tensors across the PCIe bus or NVLink fabric.
Architectural Trade-Offs: Centralized vs. Decentralized Storage
When designing an AI platform in the cloud, engineers face a fundamental architectural choice: where should the master copies of the weights live, and how should they be distributed?
A centralized storage approach keeps all weights in a primary cloud blob storage bucket. While simple to manage and secure, scaling this approach to thousands of concurrent training nodes can create severe network bottlenecks at the storage gateway. To mitigate this, enterprise architectures implement caching tiers—such as distributed NVMe scratch disks or regional caching proxies—that pull weights once from central storage and serve them locally to compute nodes.
Another critical consideration is data gravity. Because neural network weight files are immense, moving them across cloud regions incurs steep financial egress fees and significant latency penalties. Best practices dictate keeping your model training pipelines, object storage repositories, and compute clusters within the exact same availability zone or cloud region.
Conclusion
The journey of neural network weights through the cloud is a masterclass in modern systems engineering. It bridges the gap between abstract mathematical optimization and raw physical hardware. Understanding how parameters travel from cold object storage, across high-speed RDMA fabrics, through internal NVLink switches, and finally into accelerator memory is essential for building scalable, high-performance deep learning systems.
As foundation models continue to grow in scale, the synergy between machine learning algorithms and advanced AI cloud infrastructure will only tighten. By mastering the fundamentals of weight mobility, storage optimization, and network protocols, engineers can eliminate deployment bottlenecks, reduce operational costs, and build robust AI platforms primed for the demands of 2026 and beyond.